A keyless MCP server and research skill. It searches in every language, reads only the seconds that matter, sees real frames, and cites every claim with a timestamp.
“If you're starting a business this year, watch this before you spend a single dollar.”
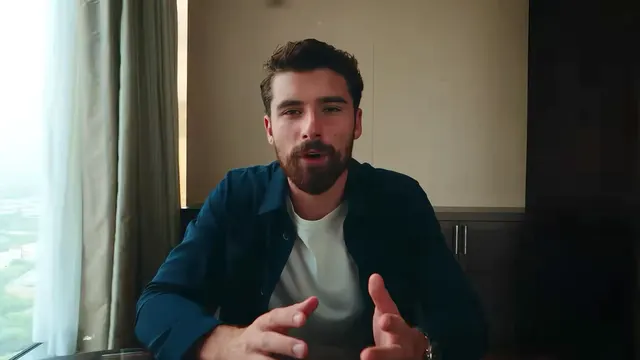
Direct calloutHandheld talking head, no text0:00
videos_reviewed: 18 · skipped: 1 (no captions) · every row links to its second
Illustrative session with AI-generated frames. Tool names, parameters and output shape are real.
WORKS WITH ANY MCP CLIENT
Claude Code
Codex
Claude Desktop
Cursor
VS Code
Windsurf
Zed
How it works
Search. Read. See. Prove it.
Four moves, each one call. The agent never wades through full transcripts it does not need.
youtube_search · one call
q1AI productivity workflowq2how I use AI at workq3AI tools I stopped usingq4automate my week with AI
4 AI agents that run my weekq1q41:36“we start with the email agent, then add the calendar…”
I quit 6 AI tools. Here's what stayed.q32:10“the biggest mistake is starting with a tool instead of a problem…”
My AI workday, start to finishq1q20:41“most people use ChatGPT like a search engine…”
Up to 12 queries in one call, each from a different angle (and, when you need it, another language or region). Results are merged and de-duplicated, videos found by several queries rank higher, and the top ones come with the transcript passages that actually match.
youtube_fetch · start 0 · end 30
0:005:0010:0015:0020:47
[0:00]Four AI agents you can build today that will save you hours of work every week.
[0:08]You don't need any technical skills. If you can type, you can build them.
[0:15]We'll do it together, step by step.
Read a time range, a chapter, or only the passages matching a query, for up to 25 videos at once. Every line keeps its timestamp; long transcripts tell the agent exactly where to continue.
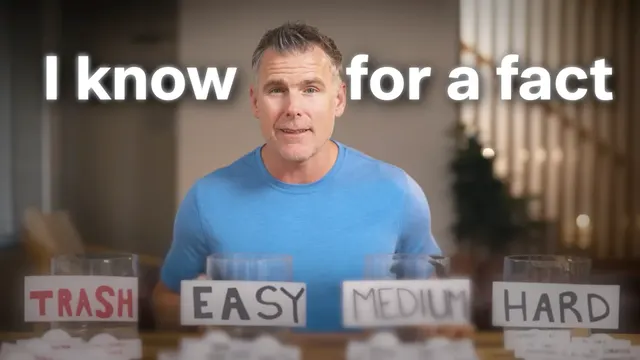
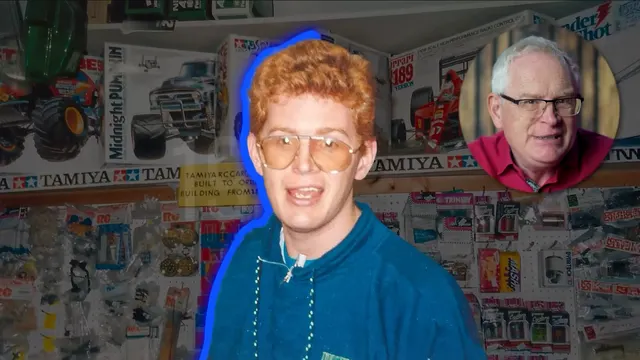
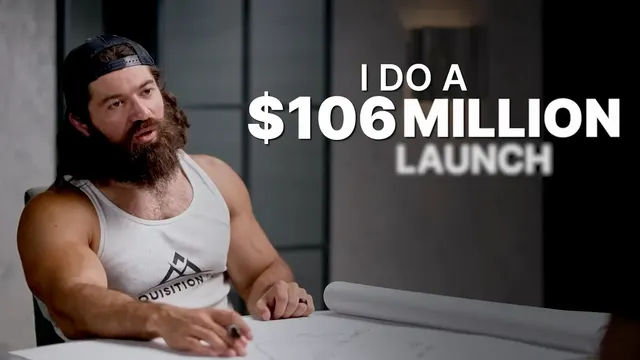
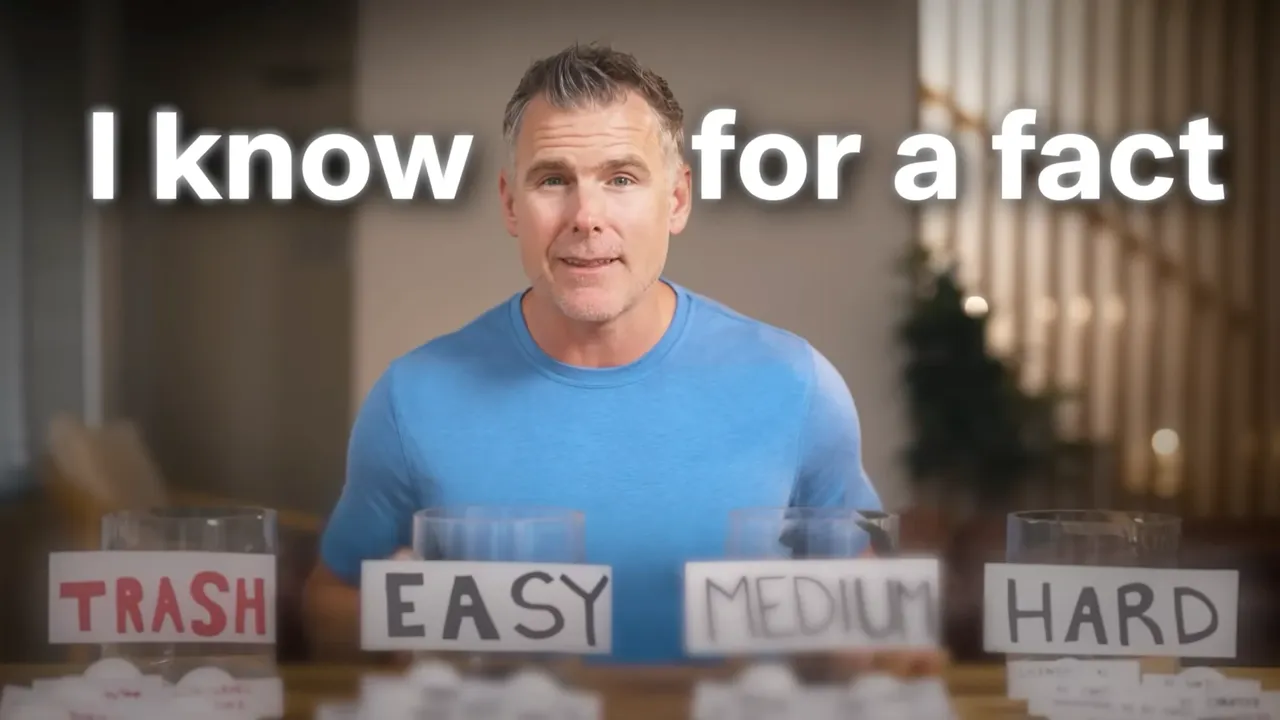
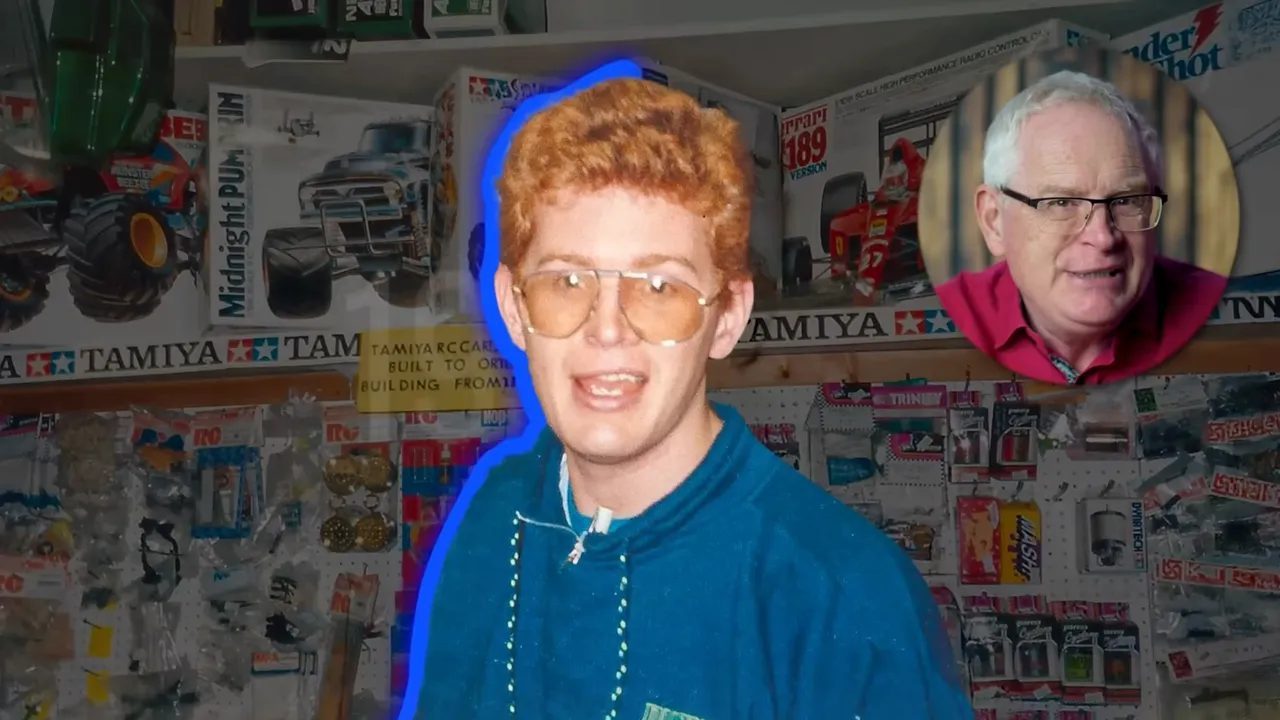
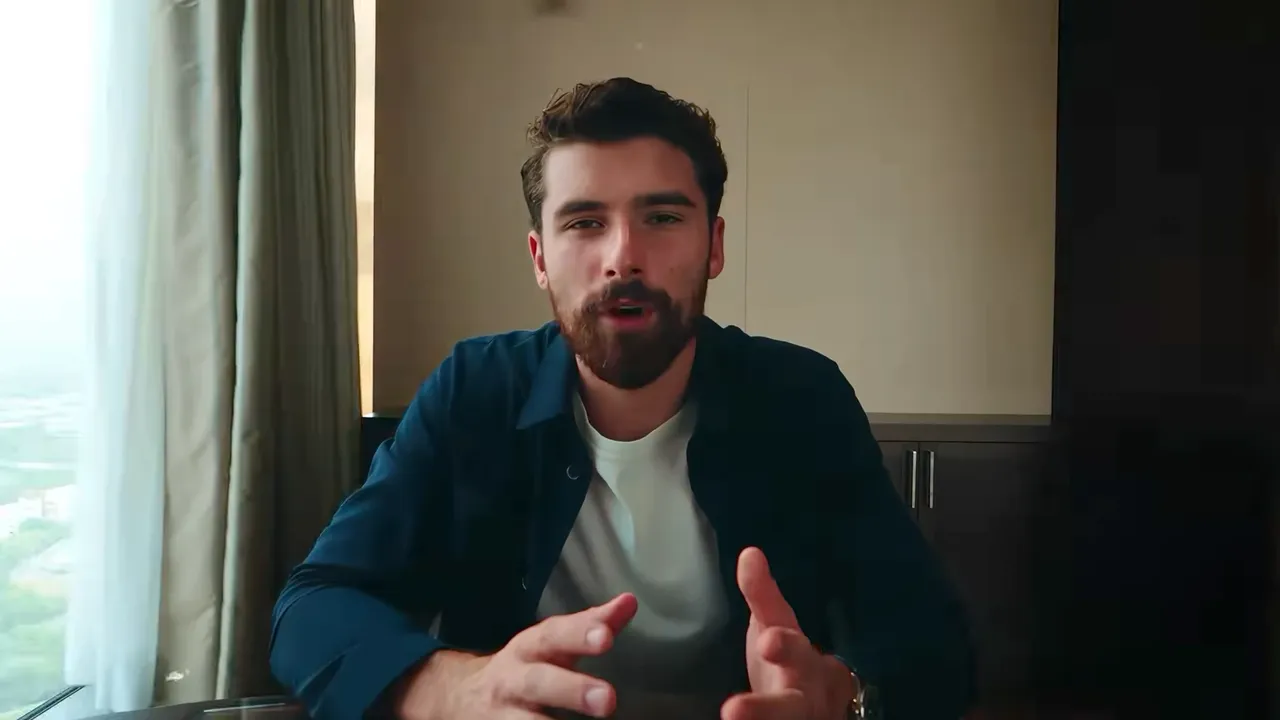
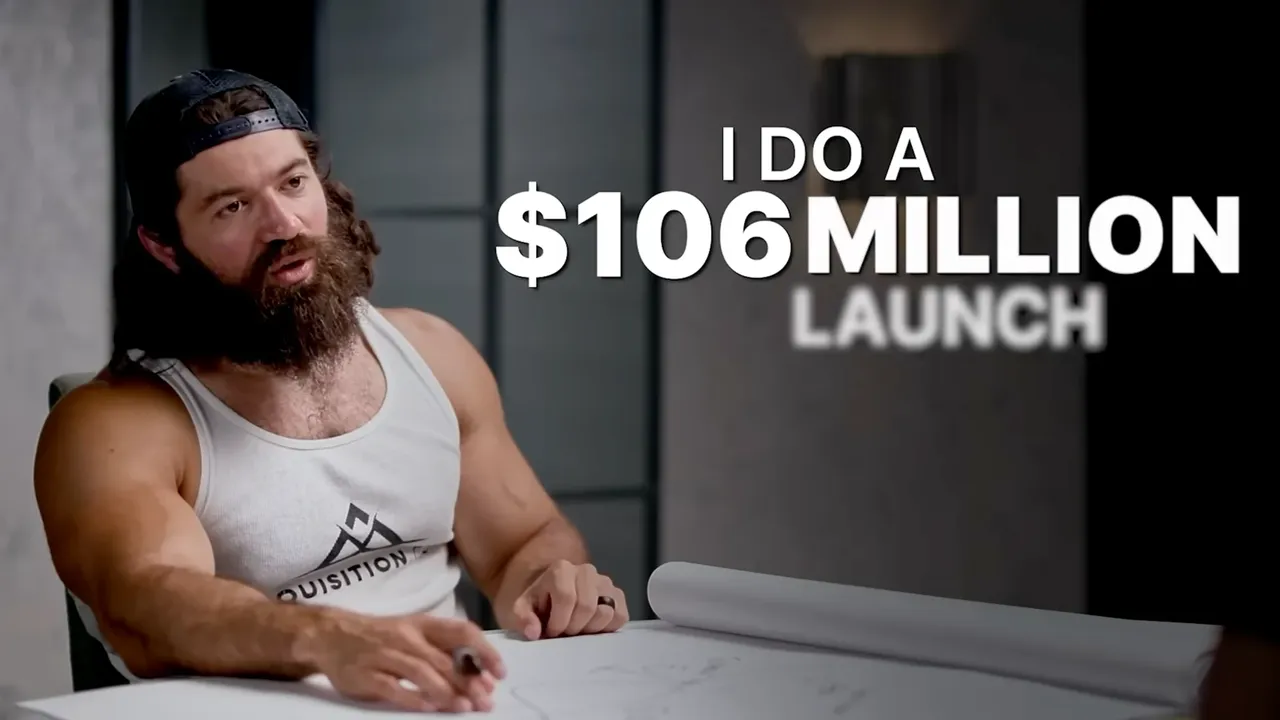
youtube_fetch · parts: frames · frames: 4
0:01
0:03
0:00
0:02
Real frames, up to 1280 px, evenly spaced over a range or at exact seconds. On-screen text, b-roll and screen demos become visible to the agent. Only the bytes around each frame are read, never the whole video.
youtube-research skill · deliverable
Quote
Type
Link
“This setup saved me 20 hours last week.”
Result first
0:00
“If your inbox owns your day, this is for you.”
Pain
0:02
“There's one setting nobody turns on.”
Curiosity gap
0:05
Coverage: 8 queries × 2 languages · 87 unique videos · 21 reviewed · 2 skipped (no captions)
Every row links to the second it came from, quotes are verbatim, and every answer ends with what was searched, reviewed and skipped. Nothing disappears silently.
The harness
Few tools. A skill that plans.
The server stays small and stateless. The research method lives in a skill: plan the queries, fan out to parallel subagents, then merge, verify and report coverage.
One research request
Your question“hooks from AI productivity videos”
youtube-research skillplans queries in every language, splits the work
4 MCP toolssearch · fetch · channel · doctor
A cited answerverbatim quotes, ?t= links, coverage
Results, not links
Search returns the transcript passages that match, so the agent often never opens a transcript at all.
Read only what you need
Ranges, chapters and query passages keep context small, even across dozens of videos.
Proof over claims
Subagents report videos_reviewed and what they skipped; the skill spot-checks quotes before answering.
0API keys or cookies
12queries per search call
25videos per fetch call
~2 stypical search with highlights
The tools
Four tools. Everything an agent needs.
youtube_search
Multi-query, multi-language search with transcript highlights and a coverage footer.
1–12 queries, each with its own hl/gl
Upload window, duration, min views, Shorts, captions
Collect the opening lines and first frames of the best videos on a topic, typed by hook pattern.
“List 20 hooks from this year's top AI productivity videos, with hook type and what's on screen.”
Creator breakouts
Find which videos beat a channel's median by 3×, then compare their titles, topics and hooks.
“Which of @channel's videos broke out this year, and what do they have in common?”
What people actually said
Verbatim quotes, claims and advice across many videos, each with the exact second.
“What do creators say is the biggest mistake with AI note-taking? Quote them.”
Multi-language scans
One topic, written natively in every market's language, merged into one de-duplicated list.
“How is ‘vibe coding’ covered in English, German and Spanish YouTube?”
Visual analysis
Frames show the setup, b-roll, on-screen text and pace of cuts: the part transcripts miss.
“How do the top 5 tutorials on Notion AI look in their first 20 seconds?”
Audience questions
Search the comments for a topic, filter by likes, sort by most liked and pull the replies, with a count of how many were scanned.
“Search the comments of these 5 Claude Code tutorials for questions about pricing, most liked first.”
Why it's different
Built for agents, not for one-off lookups.
Typical YouTube MCP
YouTube Research MCP
Search
One query per call, a list of links
Up to 12 queries and languages, merged, with transcript highlights
Transcripts
The whole transcript, every time
Range, chapter or matching passages, for 25 videos per call
Video content
Text only
Real frames at any timestamp
What worked
Raw view counts
Views/day and ×median outlier scores
Honesty
Failures dropped silently
Coverage footer and per-video reasons on every call
Rate limits
Retries until blocked
Separate caption queue, cooldown, exact wait time
Method
Left to the agent
Research skill with subagents, spot-checks and citations
Setup
Often an API key
No key, no cookies; one plugin install
Install
One prompt. Installed.
Paste one prompt into your agent. It installs the MCP server and the research skill for whatever client it runs in, then checks that YouTube is reachable.
Paste into Claude Code, Codex, Cursor or any agent
Install YouTube Research MCP for me from https://github.com/jindratilk/youtube-research-mcp. Follow the “Install instructions for AI agents” in its README for the client you are running in: the plugin (MCP server + research skill) in Claude Code or Codex, otherwise the MCP server config. Then run youtube_doctor and tell me whether everything works, and if I need to restart anything.
Prefer the terminal? Manual install
$ claude plugin marketplace add jindratilk/youtube-research-mcp
$ claude plugin install youtube-research@youtube-research
Node.js 20+Optional: yt-dlp + ffmpeg for framesmacOS · Linux · Windows
Honest limits
What it can't do (yet).
Transcripts are rate-limited
YouTube throttles caption downloads per IP. A burst of ~100 in a few minutes triggers a pause. The server stops, says how long to wait and keeps everything else working. For big sweeps, set YT_PROXY.
Search dates are approximate
Search results carry “3 weeks ago”, so date filters are ±1 unit. youtube_fetch returns the exact publish date.
No captions, no transcript
Videos without manual or automatic captions have no transcript. There is no speech-to-text in the server; frames still work.
Comment search covers the top comments
You can search, filter and sort up to 1,000 top comments per video, with replies. YouTube no longer offers anonymous clients the “newest first” sort, so it is not every comment.
Questions.
Does it need a YouTube API key?
No. It talks to the same internal endpoints the YouTube website and apps use, with no API key, OAuth or cookies. yt-dlp and ffmpeg are optional and only needed for video frames.
Which AI clients does it work with?
Any client that speaks the Model Context Protocol. It ships as a Claude Code plugin and a Codex plugin (server plus skill), and runs as a plain stdio server in Claude Desktop, Cursor, Windsurf, VS Code, Zed and others.
What is the research skill?
Instructions the agent loads for YouTube research: define the result first, plan queries in every relevant language, fan out to parallel subagents, then merge, spot-check quotes and report coverage. It includes references for hooks (with a 10-type taxonomy), quotes and claims, creator outliers and the final write-up.
Does it download whole videos?
No. Transcripts come from caption files. For frames, ffmpeg seeks inside the stream with HTTP range requests and decodes only the frames you ask for.
What happens when YouTube rate-limits it?
Caption downloads get their own slower queue. On the first 429 the server pauses transcripts instead of retrying (retries extend the block), tells the agent exactly how many seconds to wait, and keeps search, details, frames and channels working. For very large sweeps, route requests through a proxy with YT_PROXY.
Does it work with non-English videos?
Yes. Each query can carry its own interface language and region, transcripts default to the video's original language, and highlights fold accents and match inflected word forms, so a sweep across several markets lands in one de-duplicated list.
Is it affiliated with YouTube or Google?
No. It is an independent open-source project. Use it in line with YouTube's terms and respect creators' rights when you quote or reuse their content.
Does it cost anything?
No. It is free and open source under the MIT license. The code is on GitHub.
Let your agent research YouTube.
Free, open source, no API key. Claude Code, Codex and any MCP client.
 0:01
 0:03
 0:00
 0:02
 0:01
 0:03
 0:00
 0:02
